Hello and welcome back to the blog! I’m so glad you’re here.
For decades, one technology has been whispered in data centers with a certain reverence, synonymous with uncompromising data integrity: ZFS. It has a legendary reputation, and for very good reason. But in our modern world, dominated by cloud-native solutions and hyper-scale storage, you might be wondering if it’s still relevant.
My position? It’s more critical than ever.
When we talk about architecting a truly resilient, self-healing system—one that can withstand failure without waking you up at 3 AM—we have to begin at the most foundational level: the data itself. To help us unpack this, I recently sat down with someone who has built some of the most robust storage platforms in the world, Dr. Elena Vance. She’s a renowned ZFS Storage Architect, and her insights on why the principles behind ZFS are not just history, but the future of reliable infrastructure, were just too good not to share with you all.
Let’s dive into why this old-school legend is the key to your future-proof architecture.
The Magic Isn’t Magic: It’s Copy-on-Write
People often talk about ZFS in almost mythical terms. When I asked Elena about the architectural ‘magic’ that makes it so resilient, her answer was incredibly simple and profound.
The magic isn’t a single feature; it’s the foundation everything is built on: copy-on-write (CoW). Here’s the core principle: ZFS never, ever overwrites active data.
Let me paint a vivid picture for you. Imagine you’re editing a critical document. Instead of changing the original, you make a copy, make your changes on that copy, and only once you hit ‘save’ does the system instantly swap the new version for the old one. If your computer crashes mid-edit, the original document is still there, perfectly untouched.
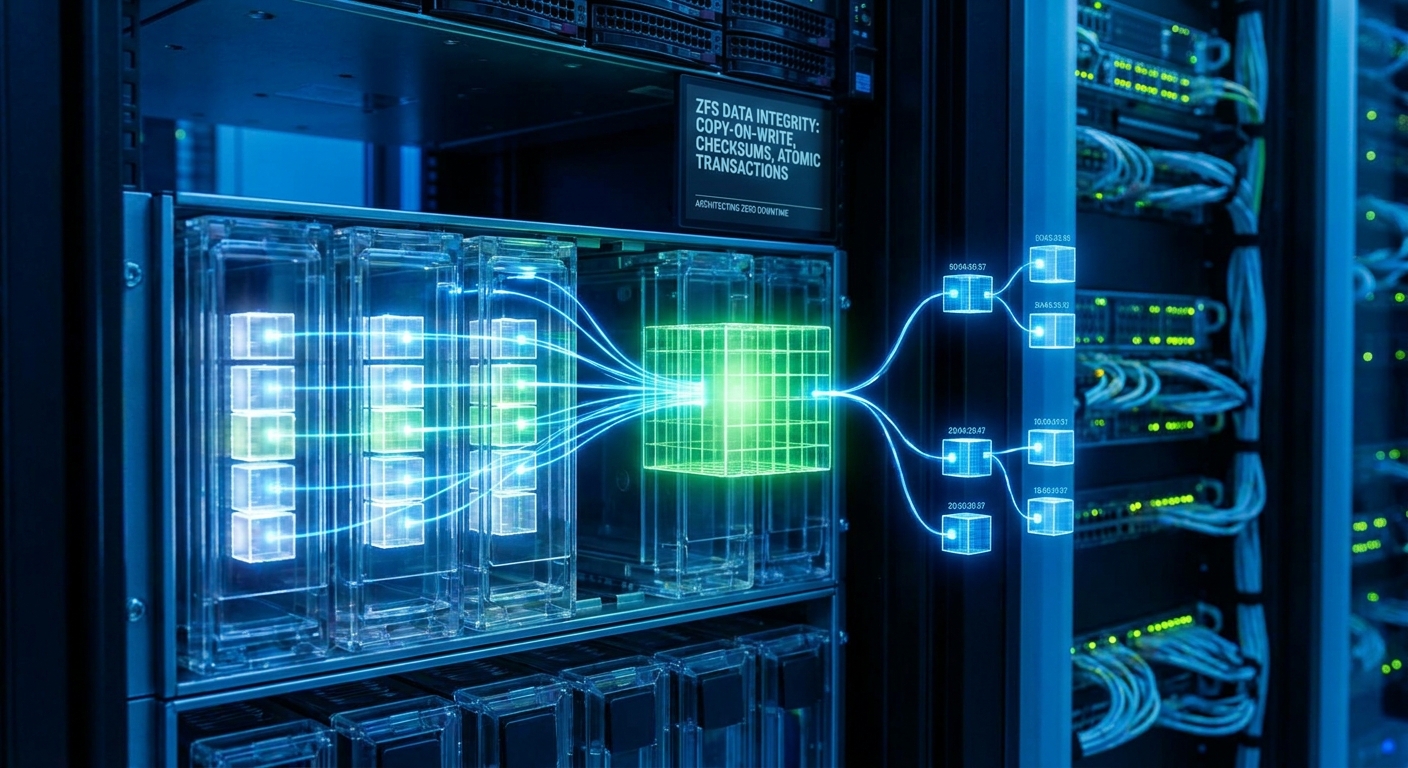
That’s exactly what ZFS does for every single block of data. When a block is changed, it writes a brand new block and then updates the metadata to point to it, all as a single, atomic transaction. If power fails mid-write, the old data is still perfectly intact. This, combined with end-to-end checksums that verify every block on read, means ZFS doesn’t just prevent corruption—it actively detects and corrects silent degradation over time. As Elena put it, it makes data corruption a solved problem, which should be the absolute baseline for any zero-downtime promise.
The Instantaneous Time Machine: Snapshots and Clones
This transactional model leads directly to two of ZFS’s most famous features: snapshots and clones.
Because ZFS never overwrites data, a snapshot isn’t a time-consuming, full-volume copy like in traditional systems. It’s just a read-only marker… a list of pointers to the data blocks as they existed at that exact moment. This means they are truly instantaneous, and they consume almost no space when you create them.
This completely changes the game for data protection. You can implement incredibly aggressive schedules. In mission-critical environments I’ve designed, taking snapshots every five or ten minutes provides a level of rollback capability that traditional nightly backups simply can’t touch.
But the real operational superpower, the part that transforms workflows, comes from clones. You can take one of those snapshots—perhaps of a live production database—and instantly provision a fully writable, independent copy from it. Suddenly, your development team has an up-to-the-minute, full-scale environment to test a critical patch, completely isolated from production. It radically improves the speed and safety of your entire development lifecycle.
Winning the War Against the “Write Hole”
This brings us to a fundamental architectural decision: choosing between a traditional hardware RAID card and ZFS’s own software-based RAID-Z. The key difference lies in a scary, and painfully common, vulnerability known as the ‘RAID write hole’.
With a hardware card, a sudden power loss during a write can corrupt your parity data, silently. You won’t know your data is damaged until you try to restore from it, which is the worst possible time to find out. ZFS’s copy-on-write model makes this impossible. The transaction is atomic, which completely eliminates that risk.
When I design these systems, I always focus on rebuild time as the key metric for availability. Today’s drives are massive, and resilvering (rebuilding) a failed drive can take many hours, or even days. During that time, your array is vulnerable. That’s why my personal rule of thumb is that RAID-Z2 (dual parity) is the absolute baseline for any serious workload. A single-parity RAID-Z1 is just too risky when a second drive failure during a long resilver could take out your entire pool.
The Ultimate Hypervisor: ZFS for VMs and Containers
This is where ZFS moves from being a robust file server to the backbone of modern infrastructure. For virtualization and containers, the design is almost perfect.
My unbreakable rule here is to place each virtual machine or container into its own ZFS dataset. This isn’t just for organization; it gives you a separate, logical file system for each workload. You can set unique snapshot schedules, compression algorithms, or quotas on a per-VM basis. It provides an incredible level of granular control.
But the performance story is what really seals the deal. ZFS uses a very sophisticated read cache in RAM called the ARC (Adaptive Replacement Cache). In a hypervisor with plenty of memory, this ARC becomes enormous and intelligently caches the ‘hot’ data from all your virtual machines. The result? A huge percentage of read I/O is served directly from system memory, which is orders of magnitude faster than any storage device. You might be surprised to find that a properly tuned ZFS system with a large ARC on spinning disks can often outperform an under-provisioned all-flash array. It’s an amazing way to build extremely high-performance systems cost-effectively.
Your Bulletproof Disaster Recovery Plan, Built Right In
Elena called this next feature a superpower, and that’s not an exaggeration. The feature is zfs send and receive, and it transforms ZFS from a single-site solution into the cornerstone of a complete disaster recovery strategy.
What I find most elegant about it is its efficiency. It doesn’t copy files; it sends a stream of the actual data blocks that have changed between two snapshots. Here’s a robust architecture I love to see in practice:
- Take a snapshot every five minutes on your production system.
- Use zfs send to calculate the precise delta—just the new data—and stream it to a warm standby server at your DR site.
This creates a continuous, low-bandwidth stream of incremental updates. It means your Recovery Point Objective (RPO) isn’t measured in hours, but in minutes. You’re achieving true business continuity without saturating your network.
Three Mistakes That Will Wreck Your ZFS Build
Of course, building a system correctly is one thing, but avoiding common pitfalls is another. I asked Elena about the architectural mistakes she sees most often, and her answer was crystal clear. Please, avoid these!
- Putting a hardware RAID card between ZFS and the disks. This is a fundamental conflict. You want a simple Host Bus Adapter (HBA) that gives ZFS direct control. A RAID card tries to be clever and fundamentally undermines ZFS’s end-to-end data integrity.
- Underestimating the need for RAM. ZFS is built around its memory cache, the ARC. Skimping on memory is the single most common cause of poor performance, especially if you plan to use the powerful, but memory-hungry, deduplication feature.
- Improper vdev design. Creating one giant RAID-Z pool is fine for streaming media, but it’s the wrong tool for a high-transaction database. For high IOPS workloads, I always design pools built from multiple mirrored vdevs. It’s all about matching the storage layout to the specific workload.
What’s Next? The Future is Self-Healing
And ZFS isn’t standing still. The OpenZFS project is incredibly active, and some of the upcoming features are genuinely transformative.
I’m watching dRAID (Distributed Spare RAID) most closely. On today’s petabyte-scale arrays, resilvering can take days—a significant window of risk. dRAID changes this by distributing parity and spare capacity across all drives, leading to dramatically faster rebuilds. It’s a game-changer for availability.
Innovations like this, and others like block cloning for virtualization efficiency, cement ZFS’s role not just as a file system, but as a foundational building block for the future of software-defined storage and hyper-converged infrastructure.
The Bedrock of Resilience
The key architectural takeaway for me, and for you, is this: stop thinking of ZFS as merely a file system. As we’ve discussed today, it’s a complete platform for data integrity and availability. Its foundational design—copy-on-write, transactional updates, end-to-end checksums—these aren’t just features. They form the very bedrock on which you can build truly resilient systems.
And that, my friends, is the ultimate goal.
That’s all we have time for today. We’ve been deep inside the logical architecture, but resilience is often undone by the physical infrastructure we take for granted. Join me next time for Episode 27: The Single Point of Failure Hiding in Your Server Rack. We’ll move from software to steel, examining the overlooked threats from power distribution units to network backplanes. It’s an area that’s often neglected until it’s far, far too late.
Until then, thank you for reading. I’d love to hear your thoughts or questions in the comments below!
Leave a Reply