Hello and welcome back to Architecting Zero Downtime Infrastructure! I am so glad you’re here with me today.
We’ve all been there, right? Staring down a project budget, looking for ways to deliver powerful, resilient systems without that hefty license fee. The open-source community is a wonderland of remarkable tools, especially for High Availability (HA) storage. But I’ve learned over the years that ‘free’ is rarely a simple proposition.
While you aren’t writing a check to a vendor, the real invoice can arrive in other ways… in the form of your time, your team’s sanity, and—most critically—your company’s uptime. So today, we are going to have a very practical, very honest discussion about the total cost of ownership for do-it-yourself HA storage.
The Allure of ‘Free’ (And the Catch)
When we talk about this space, a few big names always come up. For straightforward two-node replication, you have technologies like DRBD, which you can think of as a sort of networked RAID 1—it mirrors a block device from one server to another. Then you have the larger, more distributed file systems like GlusterFS and Ceph, designed for serious, web-scale infrastructure.
The initial appeal is undeniable. There’s no license fee. You aren’t locked into a specific hardware vendor. And there’s a vast community of brilliant people you can turn to for advice. But this is where we need to make a critical distinction. There’s ‘free as in beer,’ and then there’s the reality of the expertise, the planning, and the sheer human effort required to make these systems truly robust.
What you quickly find is that these tools trade a financial cost for an operational one.
The Split-Brain Nightmare: A DRBD Deep Dive
Let’s use DRBD as our first practical example. As I said, its core function is very elegant—it’s essentially a ‘networked RAID 1’. Any block of data written to the primary node is synchronously replicated to the secondary node over a dedicated network link. It’s clean, it’s fast, and it works.
But this elegant simplicity introduces the single most dangerous failure state in any high-availability architecture: the ‘split-brain’ scenario.
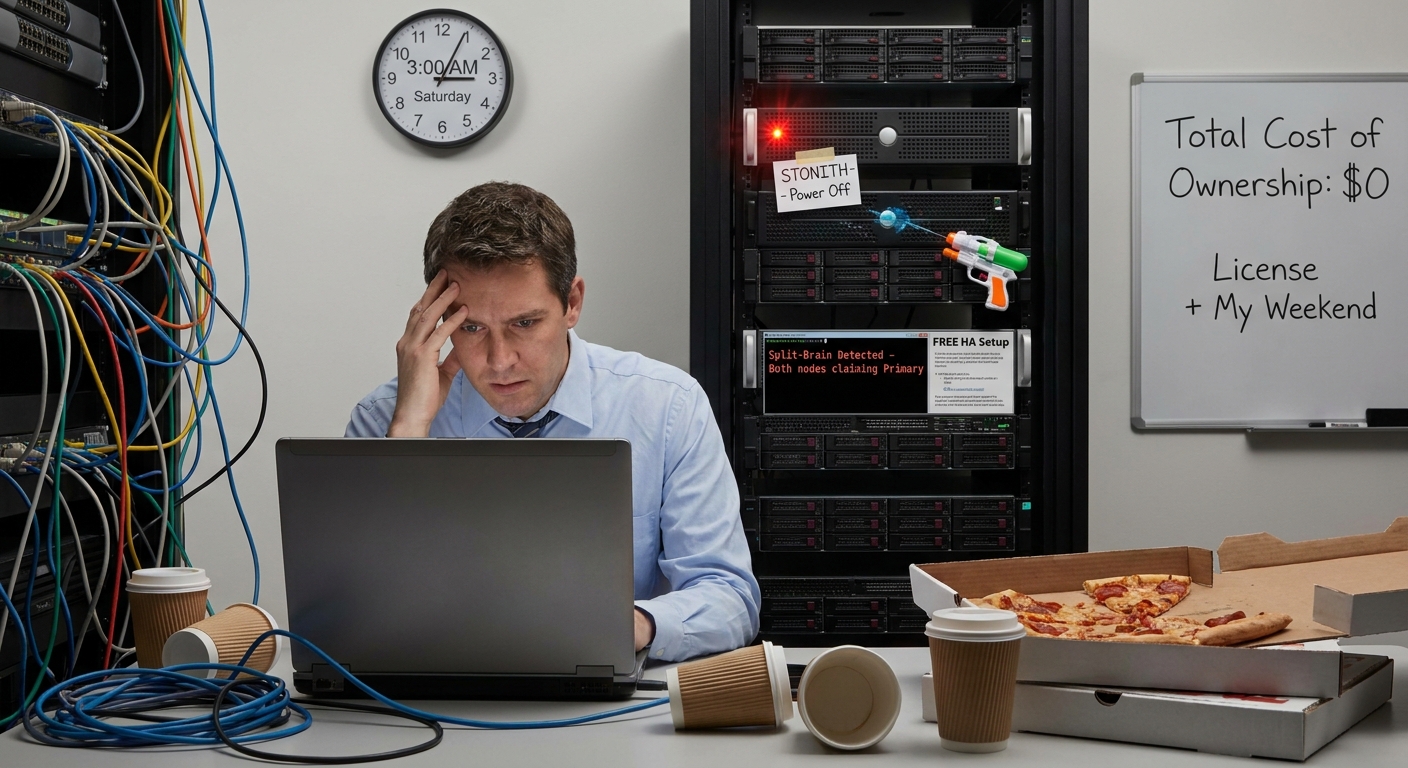
Let me paint a vivid picture for you. Imagine the dedicated network link between your two servers fails. It could be a bad cable, a faulty switch port, anything. But here’s the kicker: both servers are still running perfectly. Each node can no longer see its partner, so each one logically concludes the other has crashed. If your system is configured for automatic failover, both nodes will attempt to assume the primary role. They both believe they are the sole survivor… the active master.
At that point, both servers are accepting write operations independently. You now have two divergent, conflicting timelines for your data. When the network link is eventually restored, the system has no safe, automatic way to merge them. That, my friends, is the very definition of data corruption.
And please believe me, this isn’t some obscure edge case; it is the fundamental challenge you must solve in any two-node cluster.
My Unbreakable Rule: You Must Fence Your Nodes
So, how do we prevent this digital horror story? The only reliable way to solve the split-brain problem is a technique called fencing. And its most common implementation has a rather memorable acronym: STONITH, which stands for ‘Shoot The Other Node In The Head’.
The logic is as brutal as it is absolute. Before a standby node promotes itself to primary, it must have an absolutely guaranteed way of ensuring the other node is dead and gone. I’m not talking about a graceful shutdown request… I mean a hard, immediate, indisputable power-off.
This is often where the hidden costs begin to surface. This isn’t just a software setting. My unbreakable rule is that you must have a true out-of-band management path. This means something like a server’s IPMI or iDRAC port, or even a network-connected smart PDU (Power Distribution Unit). This is the non-negotiable component. Skipping this step to save a few dollars or a bit of complexity is probably the most common—and the most fatal—mistake I see in DIY high-availability setups.
The Complexity of Scale: Ceph and GlusterFS
Now, if we move beyond simple two-node setups, we get into the world of large-scale solutions like Ceph and GlusterFS. And make no mistake, these are immensely powerful, impressive pieces of engineering. You can use them to build petabyte-scale, self-healing storage platforms that can grow almost indefinitely.
But this is where the operational complexity can become… well, notorious.
What I often find is that the learning curve for deploying, and more importantly, tuning these systems is exceptionally steep. One day you’re a sysadmin, and the next you’re deep in the weeds of CRUSH maps in Ceph to precisely control data placement, or you’re troubleshooting subtle network performance issues between dozens of nodes. These are not ‘install and forget’ systems. When you choose this path, you’re effectively taking on the role of a storage vendor. You are building and operating a complex distributed system, and that requires a very specific and deep level of expertise to run reliably.
The Lost Weekend: A Painfully Common Story
Let me tell you a story that I find happens far too often.
It’s a Thursday, and a sharp, capable administrator sets up a ‘free’ HA cluster. They follow the guides, run all the tests, pull the network cables, and the failover works exactly as documented. It looks perfect. High-fives all around.
Then, Friday at 5:30 PM, a core switch for the replication network has a minor fault. A simple glitch. But the cluster doesn’t behave as it did in the sterile lab environment. The automatic failover fails to trigger, or worse, it triggers incorrectly and both nodes decide they are the primary.
Now, instead of heading home for the weekend, that administrator is spending their Saturday morning deciphering obscure log files, trying to manually force a failover, and validating data block by painful block to ensure nothing was corrupted.
That lost weekend, that pit in your stomach, that is the true, unbudgeted cost of ‘free’.
The 2 AM Question: Who Do You Call?
The community support model is fantastic… for certain things. When you’re learning, when you’re testing a configuration, or when you have a non-urgent question, mailing lists and forums are an incredible resource filled with generous experts.
But you have to ask yourself the hard question: what is your support model when it’s two in the morning, your entire production environment is down, and the clock is ticking?
You might find that posting a desperate plea to a forum and hoping for a timely answer is not a viable business continuity plan. This is the paradox I see so often. To make these ‘free’ solutions genuinely enterprise-ready, companies frequently end up buying enterprise support from vendors like Red Hat or SUSE anyway. You’re effectively paying to put a safety net under the free software, because when everything is on the line, what you truly need is a phone number to call and a guaranteed response time from an expert who has seen this problem a thousand times before.
Calculating the Real TCO
Having laid out all those warnings, I don’t want to suggest these tools have no place. They absolutely do, but the choice must be deliberate and appropriate.
My personal rule of thumb is this:
- Development and testing labs? An excellent choice. The stakes are lower, and it’s a fantastic environment for your team to build valuable skills.
- Non-critical workloads? Sure, if a few hours of downtime for troubleshooting isn’t a catastrophic business event.
- The sweet spot? I see them succeed most consistently in organizations that have a dedicated team of deeply skilled Linux and storage engineers. These are companies that effectively decide to treat their storage platform as an in-house developed product. They have the staff, the expertise, and the culture to manage that complexity.
In the end, the choice isn’t just about the software; it’s about the human resources you can commit to it. So let’s properly calculate the real Total Cost of Ownership. What I always push for is an analysis that goes far beyond the software license (which is zero).
- Engineer’s Time: Not just for the initial setup, but for the ongoing care, feeding, patching, and emergency troubleshooting.
- Specialist Hardware: The dedicated 10-gigabit networks for replication, and the essential out-of-band management cards we discussed.
- Formal Training: To get your team up that steep learning curve.
- The Big One: The potential business cost of downtime, which is the hardest to quantify until it’s too late.
When you add all of this up, you might find that a fully-supported commercial solution isn’t just about reducing risk. In many cases, it’s simply the more financially sound decision from day one.
It’s a Trade, Not a Savings
The key message I’d like you to take away today is that choosing ‘free’ storage HA is not truly about saving money. It’s about making a conscious trade. You are exchanging a predictable capital expense for the less predictable operational costs of your engineers’ time, the need for very deep expertise, and a different, often higher, level of operational risk.
Before you choose your path, my advice is to perform a thorough, honest TCO analysis. Look beyond the sticker price and be realistic about what your team and your business can truly support.
Speaking of powerful tools that demand that kind of expertise to avoid problems… that brings us neatly to our next episode. Join me next time for Episode 25: ‘Common ZFS Pitfalls and How to Avoid Them’, where we’ll learn how to sidestep the traps in this truly remarkable, but often misunderstood, filesystem.
Thank you for listening, and I can’t wait to see you in the next one. As always, leave your questions and comments below—I read every single one!
Leave a Reply